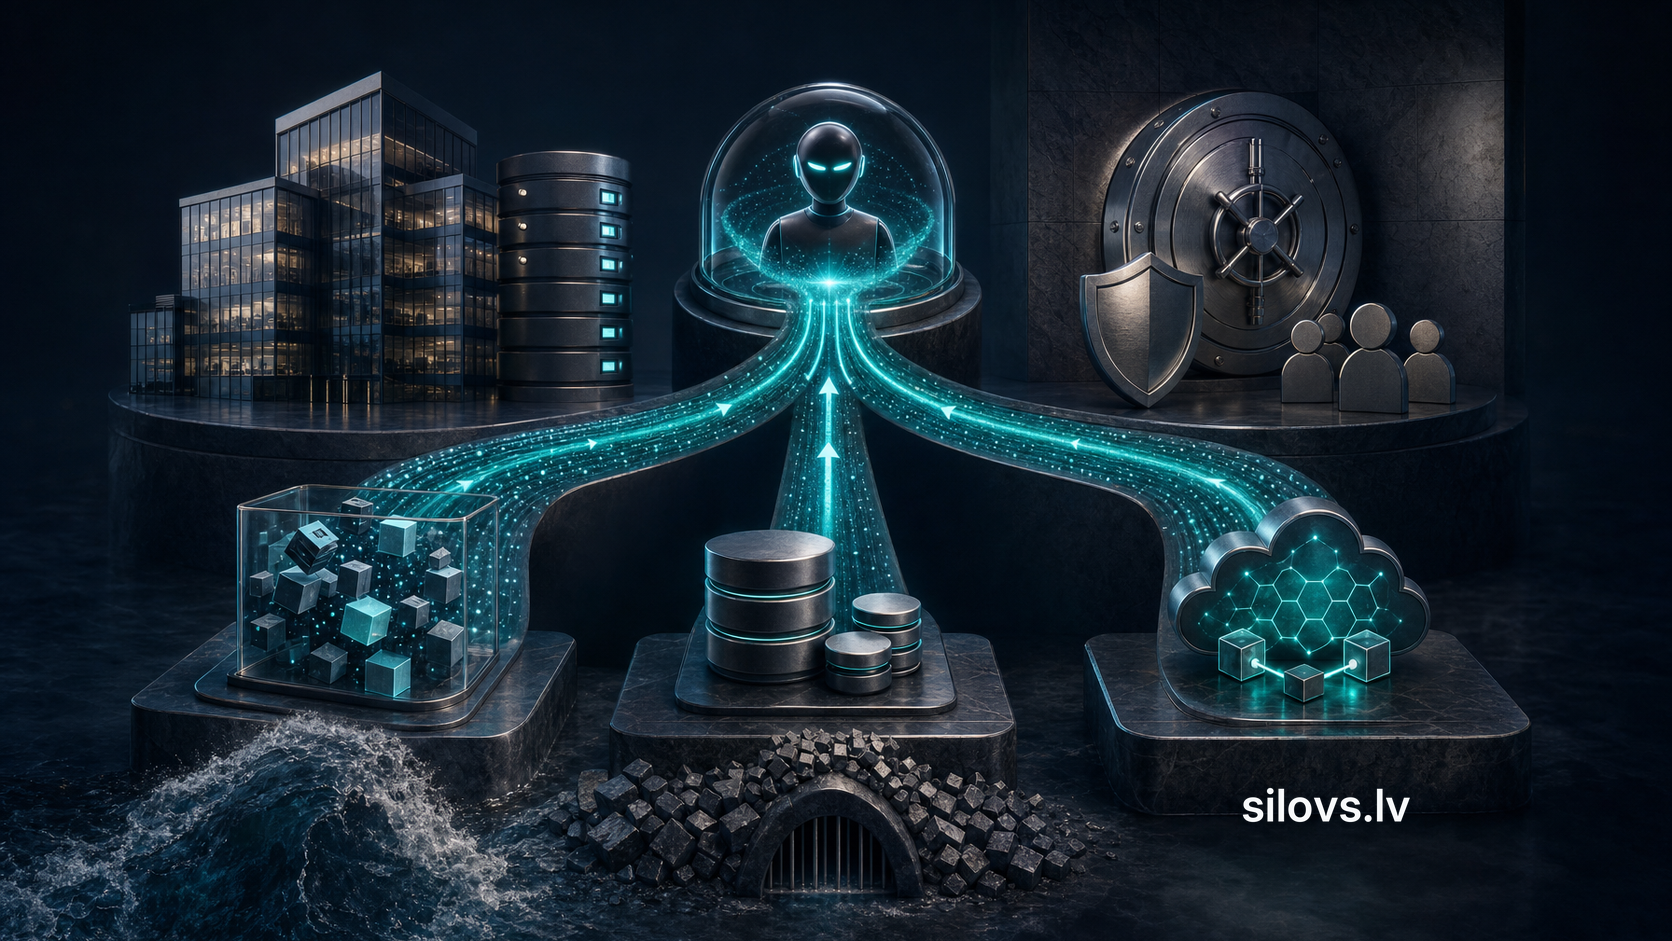
The short answer: RAG is better suited to documents and knowledge that can be indexed, while controlled API access is better for data whose current state must be retrieved at the time of the request. If an assistant needs both rules and the current status of a customer, order or stock level in one answer, a hybrid approach is usually required. The model should not have unrestricted database access: it calls narrowly defined tools, while the server checks the user, permissions, parameters and result.
The practical decision therefore involves more than choosing between RAG and API access. You must determine which data is authoritative, how stale it may be, what a specific user is allowed to see, and whether the assistant will only provide an answer or also change data.
What RAG and direct API access mean in this context
RAG, or retrieval-augmented generation, is a process in which the system finds passages relevant to a question in a knowledge source before answering and places them in the model’s context. The source may be an index of policies, instructions, product descriptions, contract templates or other documents. The model does not receive the entire document repository; the retrieval layer selects a relatively small amount of context for the specific question.
In this article, direct API access means a controlled tool or function call at runtime. For example, the assistant may request get_order_status, find_customer_invoices or check_stock, while the API middleware defines the permitted operations and communicates with a CRM, ERP or another source system. “Direct” does not mean giving the model a database password or allowing it to construct arbitrary SQL queries.
The key difference is when the data is retrieved. RAG usually uses a prepared index whose freshness depends on synchronisation. An API reads the state of the source system at the time of the request, although the result is only as current and accurate as the source system itself.
Comparing RAG and API access by decision criteria
|
Criterion |
RAG |
Controlled API access |
|
Most suitable content |
Documents, policies, instructions and descriptions |
Structured records, statuses, balances and calculations |
|
Freshness |
Depends on indexing frequency and errors |
State of the source at the time of the call |
|
Retrieval |
By semantic and textual relevance |
By defined parameters and operations |
|
Access control |
Must also be enforced when selecting passages |
Must be checked for every endpoint and object |
|
Source attribution |
Can show the document and passage |
Can identify the system, record and retrieval time |
|
Data operations |
Usually intended for reading |
Can read or change data if deliberately permitted |
|
Main failure risk |
Stale, irrelevant or incomplete passage |
Incorrect parameter, unavailable system or unauthorised action |
|
Implementation complexity |
Document preparation, indexing and retrieval quality |
API contracts, authorisation, validation and error handling |
The table does not provide an automatic verdict. For example, a product catalogue can be indexed in a RAG system if changes are infrequent, but a frequently changing price or stock level should be requested from the source system. The choice is determined not by the name of the data, but by the acceptable staleness and the consequences of an incorrect answer.
When RAG is a justified choice
RAG is useful when the basis for an answer is found in documents and the user’s question cannot be reduced to a single precise database field. An employee might ask how a discount is approved within the company, which documents are required for customer onboarding, or what a particular warranty policy provides for in an unusual situation. In these cases, semantic retrieval helps find related passages even when the question does not use the document’s exact terminology.
However, this method does not ensure freshness by itself. You must define which documents may enter the index, who approves their status, how a new version is handled, and how quickly changes become available to the assistant. If the old and new policies are indexed simultaneously without version markers, the model may receive conflicting context.
RAG is not a good default choice for an exact account balance, today’s order status or a delivery date recalculated in an operational system. Copying such data into a retrieval index may be technically possible, but synchronisation lag creates unnecessary uncertainty about the true state.
When controlled API access is required
An API is more suitable when the answer depends on a current structured record or a deterministic calculation. Typical examples include a customer’s unpaid invoices, the current stage of an order, available quantity, reservation status or a delivery calculation. The model determines which permitted tool to use, but the business system remains the authoritative data source.
A secure API integration starts with a narrow operation rather than universal access. The tool should accept only the required parameters, validate their format and return a response that excludes unnecessary personal or commercially sensitive data. The user’s identity, company and role must not be trusted when supplied as an argument generated by the model. The server must obtain this context from an authenticated session and check it against the specific object.
Reading and writing also do not carry the same level of risk. It is often sensible to allow read-only access in the initial version. If the assistant creates an order, changes an address or sends an invoice, additional validation, a user-readable preview of the action, confirmation, an audit record and safe handling of repeated requests are required.
Why a hybrid architecture often wins in practice
Many business questions combine stable knowledge with a changing state. The question “Can this order be cancelled, and how much will be refunded?” requires the system to find the cancellation rules in documents, retrieve the order status and possibly call a company-approved calculation. RAG explains the applicable procedure, while the API provides data for the specific case.
In a hybrid system, an orchestration layer chooses the order of sources, combines the results and preserves traceability. The answer should distinguish a rule found in a document from a fact retrieved from a system. If one source is unavailable, the assistant must not fill the gap with a plausible guess; it should state which part could not be verified.
An implementation sequence that starts with data, not the model
1. Describe the questions to be answered and the permitted actions
Start with specific user questions rather than a requirement to “connect AI to all company data”. For each question, record the required source, data owner, acceptable staleness and consequences of an error. Mark separately the actions that only read information and those that change the state of a system.
2. Identify the authoritative source
Each fact should have a clearly defined primary source. If a customer’s status differs between the CRM, accounting system and a spreadsheet, an AI assistant will not resolve that data governance problem. Before integration, agree which system supplies the answer and how conflicts will be handled.
Documents need a status, version, effective date, owner and access classification. API results benefit from a record identifier, source system and retrieval time. These fields help both to explain the answer and to investigate incidents.
3. Classify data by freshness and sensitivity
Define the maximum acceptable staleness for each type of data. “Current” is not a universal technical property: an internal manual may have one requirement, while a price or stock level has another. The RAG synchronisation schedule should be derived from this requirement, not the other way round.
At the same time, classify personal data, financial information, trade secrets and public content. Only the minimum required to prepare the answer should enter the index or the model’s context. The access filter must be applied before a passage or API result is passed to the model.
4. Design narrow RAG sources and API tools
On the RAG side, retain the document’s identity and version, divide content into meaningful passages and provide for the removal of old versions. Retrieval results should include source metadata so that the answer can be verified.
On the API side, create task-specific tools with clear input and output schemas. get_order_status(order_id) is more controllable than a universal query_database(query). The server must check parameters, object ownership, user permissions and the permitted scope of data regardless of what the model requests.
5. Define behaviour for failures and uncertainty
The system must know what to do when retrieval finds insufficient evidence, sources conflict, the API does not respond or the user lacks permission. A safe response may be a refusal, a clarifying question or escalation to a person. This is not a technical shortcoming but a deliberate control.
For write operations, include a confirmation step and protection against duplication. If the same request is repeated after a network error, it should not create a second order or execute the action twice.
6. Create an auditable event log
The log should connect the user, question, selected documents, called tools, permission decision, result status and final answer. Sensitive data in logs should be limited, but without any traceability it is impossible to understand whether an error originated in the source, retrieval, API or the model’s interpretation.
Example: a customer service assistant
Suppose an employee asks: “Why can’t the customer’s order be dispatched yet, and what should I tell them?” The system could proceed as follows:
- Obtain the employee’s identity and access role from the authenticated session.
- Use the API to retrieve the status of the specific order, any outstanding actions and the latest changes.
- Find the current customer communication procedure for the relevant cause of delay in the RAG index.
- Prepare a draft response that distinguishes operational facts from the policy basis.
- If the order API is unavailable, do not provide an invented reason; explain that the status cannot currently be verified.
RAG alone would not know the order’s current state, while an API alone would not explain the approved communication procedure. A hybrid solution combines both sources without confusing their roles.
Limitations and risks that architecture does not eliminate
Stale data. A RAG index may lag behind the document repository, while an API may accurately return a poorly maintained source record. Both synchronisation and data quality at the source must be controlled.
Incorrect authorisation. Permission to use the assistant does not mean that a user may view all of its sources. Permissions must be checked at the level of document passages and business objects. The zero trust principle means that access is not granted solely because of location or initial authentication.
Prompt injection. A document, web content or tool result may contain text that attempts to change the assistant’s behaviour. Retrieved content must be treated as data, not as trusted system instructions. Tool arguments created by the model are also untrusted input that the server must validate.
Model interpretation errors. A correct passage or API result does not guarantee a correct conclusion. The model may confuse dates, subjects or conditions. High-risk decisions require deterministic rules or human review, not merely wording generated by a language model.
Availability and costs. A hybrid answer may depend on several systems, increasing latency and the number of failure points. Call limits, timeouts, caching boundaries and a fallback process must be defined without silently sacrificing data freshness.
How to measure whether the chosen approach works
Do not assess the system solely by whether its answer sounds convincing. Create a representative set of questions with expected sources, permission scenarios and correct failure behaviour. Test normal, ambiguous, unauthorised and technically unsuccessful requests separately.
Practical metrics include:
- how often the answer is supported by the correct document or system record;
- whether the document version and data used meet the freshness requirement;
- how often the required tool is selected and called with valid parameters;
- whether unauthorised access attempts are blocked;
- the error rates for the API, retrieval and final answer;
- response time and the number of calls to external systems;
- the quality of justified refusals or escalation to a person.
RAG retrieval quality and API operation quality should be measured separately. Otherwise, a good final answer may conceal an incorrect source selection, while poor wording may obscure the fact that the data retrieval layer worked correctly.
A short selection checklist
Choose RAG if the required answer is primarily found in managed documents and showing the supporting passage is important. Choose an API if you need a current structured state, an exact calculation or a controlled action. Choose a hybrid approach if the specific case must be interpreted according to documented rules.
Before implementation, answer four questions: which source is authoritative, how old the data may be, who is allowed to see it, and what the system will do if the source is unavailable. If there are no specific answers, choosing a model will not solve the problem.
Conclusion
RAG and API access are not interchangeable technologies. RAG gives the model selected documentary context, while an API allows it to retrieve the state of a specific business object or perform an operation in a controlled way. A secure AI assistant uses each approach for its intended purpose, preserves source traceability and does not present unavailable information as a known fact.