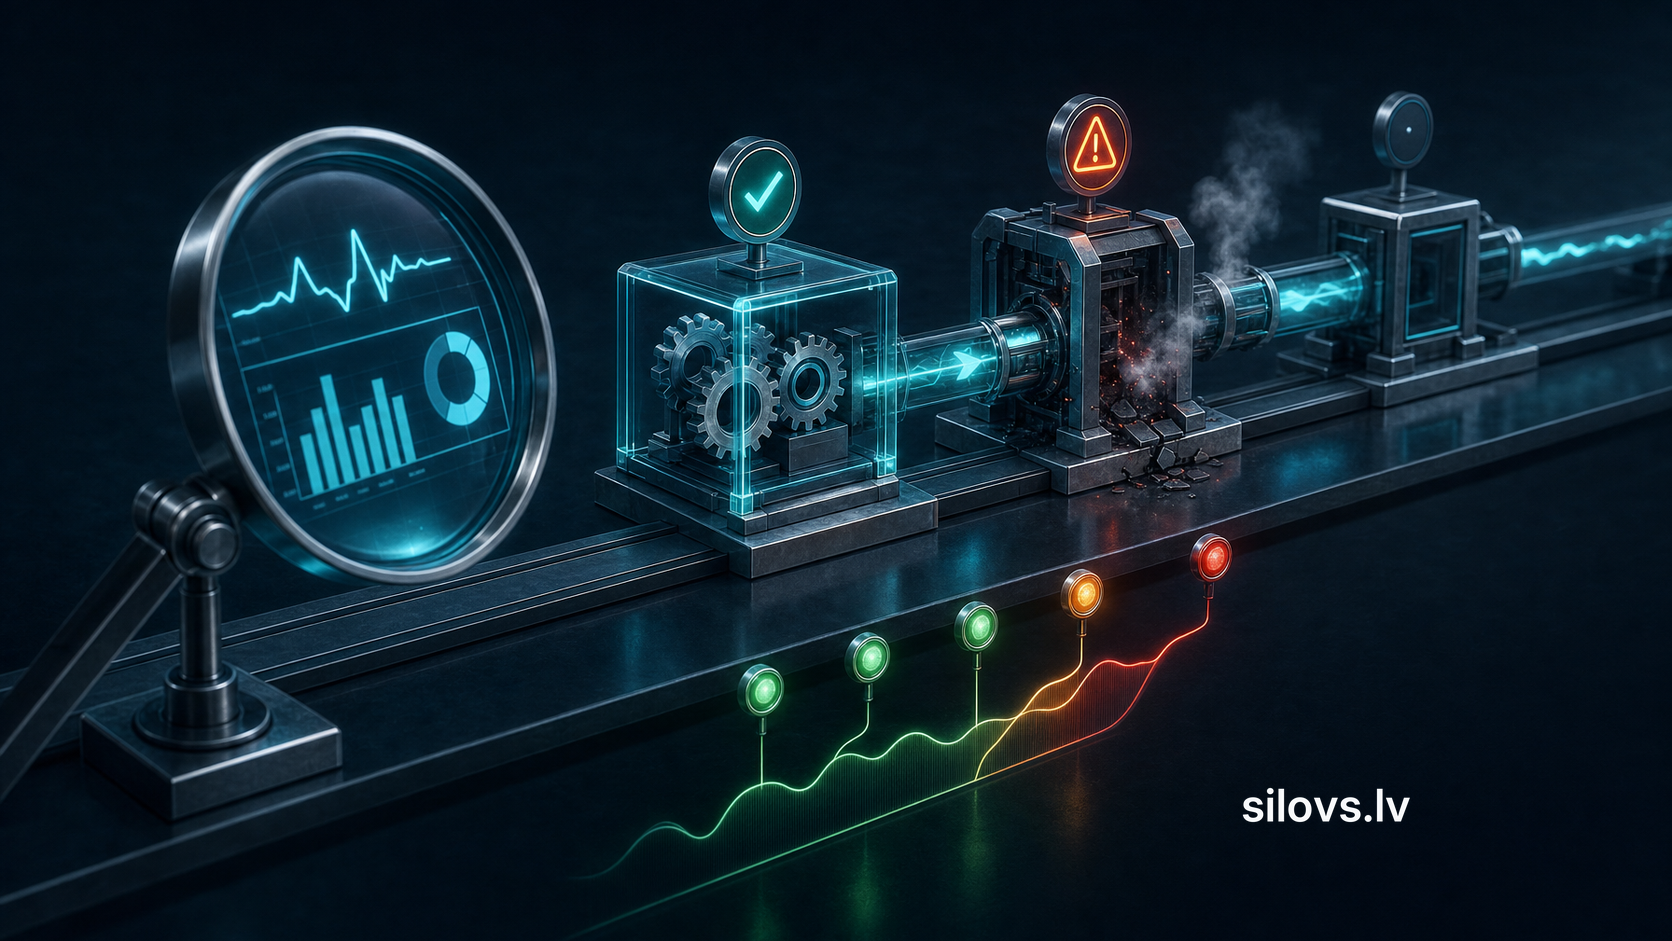
Automation monitoring should reveal two things: whether the system is technically operational and whether work is being completed correctly, on time and without increasing manual intervention. The earliest signs of degradation are usually rising execution times, an ageing queue, more frequent retries, declining data quality and a deviation from the expected processing volume. By contrast, the error rate and a missing business outcome often confirm that a problem already exists. A practical monitoring system therefore combines technical, workflow and business KPI, sets contextual thresholds for them and assigns every significant alert to a specific owner and response plan.
What it means for a workflow to start degrading
An automation can be degraded even when its status says it is “running”. Requests are still being received and some runs still complete successfully, but results arrive increasingly late, the number of unprocessed items grows or the system starts accepting incomplete data. Waiting for a complete failure in this situation is too late.
Monitoring should cover three interconnected levels:
- Technical execution — whether services, connections, jobs and external dependencies respond.
- Workflow health — whether items move through every stage without growing queues, delays or reprocessing.
- Business outcome — whether the correct invoice has been created, an application has been sent, a status has been updated or the process has fulfilled its other intended purpose.
If only the first level is measured, a semantic error may go unnoticed: the API returns a successful status, but a field contains the wrong value. If only the business outcome is measured, the problem becomes visible too late. Both early indicators and outcome-confirming metrics are therefore necessary.
KPI that reveal automation degradation
The Google SRE approach to monitoring highlights latency, traffic, errors and saturation as a starting point. These technical signals alone are insufficient for an automated business process, but they help structure the measurements. A practical KPI set should also include metrics for queues, data quality and business outcomes.
|
KPI |
What it shows |
What a deviation may mean |
|
Proportion of successfully completed runs |
How many items reach the intended final status |
An integration, validation or business-rule error |
|
Execution time |
How long an item takes to move from start to outcome |
A slow dependency, blocked stage or lack of resources |
|
Processing volume |
How many items are processed within a given period |
An interruption in input or reduced system throughput |
|
Queue length and age of the oldest item |
Whether work is accumulating and how long it has been waiting |
The consumption rate is falling behind the incoming flow |
|
Retry rate |
How often an operation fails on its first attempt |
An unstable external service or timeout problem |
|
Number of unrecoverable errors or dead-letter items |
How many items are no longer processed automatically |
A need for manual investigation or data correction |
|
Data validation errors |
Whether input data conforms to the expected structure and rules |
Changes in the source system or poor-quality input |
|
Manual takeover rate |
How often a person must complete an automated process |
Growth in incomplete rules, exceptions or degradation |
|
Number of duplicates and reconciliation discrepancies |
Whether the same outcome is retained across systems |
Repeated calls, idempotency issues or synchronisation problems |
|
Business outcome rate |
Whether a technically completed operation produces the required outcome |
A silent semantic error that the technical status does not reveal |
Not every metric needs to trigger an immediate alert. Some KPI are intended for trend analysis, while others indicate an incident requiring action. For example, a single retry may be normal protection against a temporary connection failure. A sustained rise in retries combined with an ageing queue shows that the workflow is no longer able to recover.
Measure the distribution, not only the average
Average execution time can conceal a small but commercially important group of extremely slow items. Alongside the average, assess percentiles or at least distinguish ordinary runs from exceptionally long ones. Segmentation may also be needed by process type, customer group, integration, data source and error category where such distinctions are justified by the business.
A successful execution status must also be defined precisely. If an application has been written to a database but has not reached the CRM or been assigned to an owner, that technical intermediate step is not a business success. The final KPI should be tied to a verifiable outcome rather than the most convenient system event.
Percentage metrics can be misleading in low-volume processes because a single error can change the rate sharply. In this case, percentages should be considered alongside the absolute number of items, waiting time and the importance of the particular item.
How to set meaningful alert thresholds
There is no universal threshold for error rate or execution time. It depends on the process’s business criticality, normal variability, seasonality, data volume and the time available for the team to prevent harm. A good threshold separates normal fluctuation from a condition that requires a decision.
Start with a historical baseline from normal operating periods. Assess working days, overnight jobs, month-end and other predictable volume patterns separately. Then define:
- the expected range, which requires no response;
- a warning state, in which the trend should be investigated before the outcome is affected;
- a critical state, in which customers, finances, data or deadlines may be harmed;
- a recovery condition, which determines when the incident has genuinely ended.
A static threshold suits a stable workflow with a clear limit—for example, an item must not wait longer than a defined business deadline. A dynamic threshold is more suitable for variable volumes, but it can accept slow degradation as the new normal. Dynamic anomaly detection should therefore not be used without an absolute business limit.
A periodic job also needs an absence alert. If an overnight import does not start at all, the error rate may remain at zero because there have been no runs. The absence of an expected start, completion or heartbeat event reveals this type of problem.
A good alert explains what to do
An alert should not merely repeat the metric. It should provide enough context for the owner to determine the scale of the problem and the first check to perform. A practical notification includes:
- the workflow and environment name;
- the affected stage and observed symptom;
- when the deviation began and how long it has lasted;
- the number of affected items or items waiting in the queue;
- the time of the last successful run;
- a link to the dashboard, logs or investigation guide;
- the responsible role and escalation procedure.
An informational notification can be included in a report. A warning requires investigation within a defined working period. A critical notification should trigger an immediate response only when delay creates a significant risk. If every signal is critical, the team becomes accustomed to the noise and may miss a genuinely important incident.
Prometheus alerting guidance recommends focusing on symptoms visible to the user or service rather than creating a notification for every possible technical cause. In automation, this means that queue age or a missing outcome is often a more valuable signal than an isolated temporary connection error.
What data is needed for diagnosis
A metric shows that something has changed; a log helps explain a specific event; tracing shows an item’s path through multiple services. In the OpenTelemetry observability model, metrics, logs and traces are complementary telemetry signals. Business process events must be added deliberately because a technical tool does not inherently know what “completed correctly” means to the organisation.
Every processed item needs a correlation identifier, stage status, start and end time, error category and processing-attempt number. It is also advisable to record the rule or integration version so that behaviour introduced by a change can be distinguished from previous behaviour.
Full customer documents, access credentials or other sensitive data should not be copied indiscriminately into logs. Identifiers, statuses and safely selected fields are usually sufficient for diagnosis. Access to monitoring data should be restricted according to its contents.
Example: transferring a customer enquiry to a CRM
Suppose a website form validates an enquiry, creates a contact in the CRM, assigns an owner and sends a confirmation. A single “form is working” metric is insufficient.
Early signals would include rising execution times for CRM requests, retry frequency and the age of enquiries in the queue. The outcome KPI would check whether exactly one CRM record has been created for every valid form submission within the defined period, an owner has been assigned and the confirmation status has been recorded. A reconciliation check would compare enquiries accepted by the form with records created in the CRM.
If the CRM is temporarily unavailable, a retry is not in itself an incident. If the queue continues to age or unrecoverable rejected items appear, the process owner should be alerted. If retries can create multiple contacts, monitoring should be supplemented with idempotency controls and duplicate checks. Any manual action required after an error belongs to the design of the fallback process, not merely to monitoring.
A dashboard should support a decision
A single view does not need to contain every available metric. An operational dashboard should answer four questions: is the workflow currently operating, is work accumulating, which stages are affected and is the business outcome being achieved? A trend view should additionally show changes in error categories, manual work, data quality and processing time.
An overall green status must not conceal a critical segment. If one integration or a particular type of work is degraded, the dashboard should make it possible to separate it from the rest of the workflow. At the same time, the number of segments must remain manageable; otherwise, each segment will contain too little data and the overview will become difficult to interpret.
Implementation sequence
- Define the process outcome. Specify exactly what confirms successful completion and how long the outcome may be delayed.
- Divide the workflow into stages. For each stage, identify the input, output, dependency, owner and possible exceptions.
- Implement event recording. Add correlation identifiers, timestamps, statuses and error categories.
- Establish a baseline. Observe normal operation under different volume patterns before setting aggressive thresholds.
- Choose a small set of critical KPI. Include at least the outcome, execution time, queue health, errors and manual takeover.
- Link alerts to actions. Specify the responsible role, initial checks, escalation and manual fallback path.
- Test the monitoring system. Simulate dependency unavailability, invalid data, a stuck queue and a periodic job that does not run under controlled conditions.
- Review signal quality. Assess which notifications prompted action, which were noise and which incidents the system failed to detect.
Monitoring is not a dashboard that is configured once. When process rules, integrations or business deadlines change, measurement definitions and thresholds must also be reviewed.
Limitations and risks
Monitoring data cannot compensate for an unclear process definition. If there is no agreement on what constitutes a correct outcome, precise technical measurements will merely describe an ambiguous system in detail.
A historical baseline can be misleading after significant business or technology changes. Seasonality and small data volumes create false anomalies, while slow degradation may not cross a dynamic threshold. Overly sensitive notifications, in turn, cause alert fatigue.
Not every error is visible in infrastructure data. An incorrectly calculated amount, a wrongly assigned status or a message sent to the wrong recipient may complete technically without an error. Such risks require business validations, reconciliation checks and sometimes sample-based quality control.
KPI can also encourage undesirable behaviour. A team may improve average execution time by postponing more complex cases or reduce the error rate by reclassifying failures. Speed metrics should therefore be considered alongside quality, deferred work and the final outcome.
A short checklist for the process owner
- Has a verifiable final business outcome been defined?
- Are the error count, queue age and execution time visible?
- Is it possible to trace one item through every stage?
- Does a periodic job failing to start generate a signal?
- Does every alert have an owner, priority and response instruction?
- Are critical thresholds based on business impact rather than a convenient round number?
- Are duplicates, discrepancies and manual takeovers monitored?
- Are sensitive data being stored unnecessarily in logs?
- Are KPI and thresholds reviewed after process changes?
Related questions to consider next
Building a monitoring system is closely linked to process mapping, error handling and idempotency. This topic is therefore logically complemented by the articles “Business process mapping before automation”, “What happens when automation fails: how to design error handling and a manual fallback process” and “Idempotency in integrations: how to prevent duplicate invoices and orders”. Each addresses a different question: what to measure, how to respond after an error and how to prevent harm from repeated processing.
Conclusion
Useful automation monitoring starts with the business outcome and works backwards to the technical signals. The most valuable way to detect a problem early is usually a combination of indicators: execution time rises, the queue ages, retries become more frequent and the proportion of correctly completed items falls. An alert becomes valuable only when it is timely, explainable and linked to a specific action. The signal must arrive early enough to restore the process before significant harm occurs. Collecting as many metrics as possible is not an end in itself.