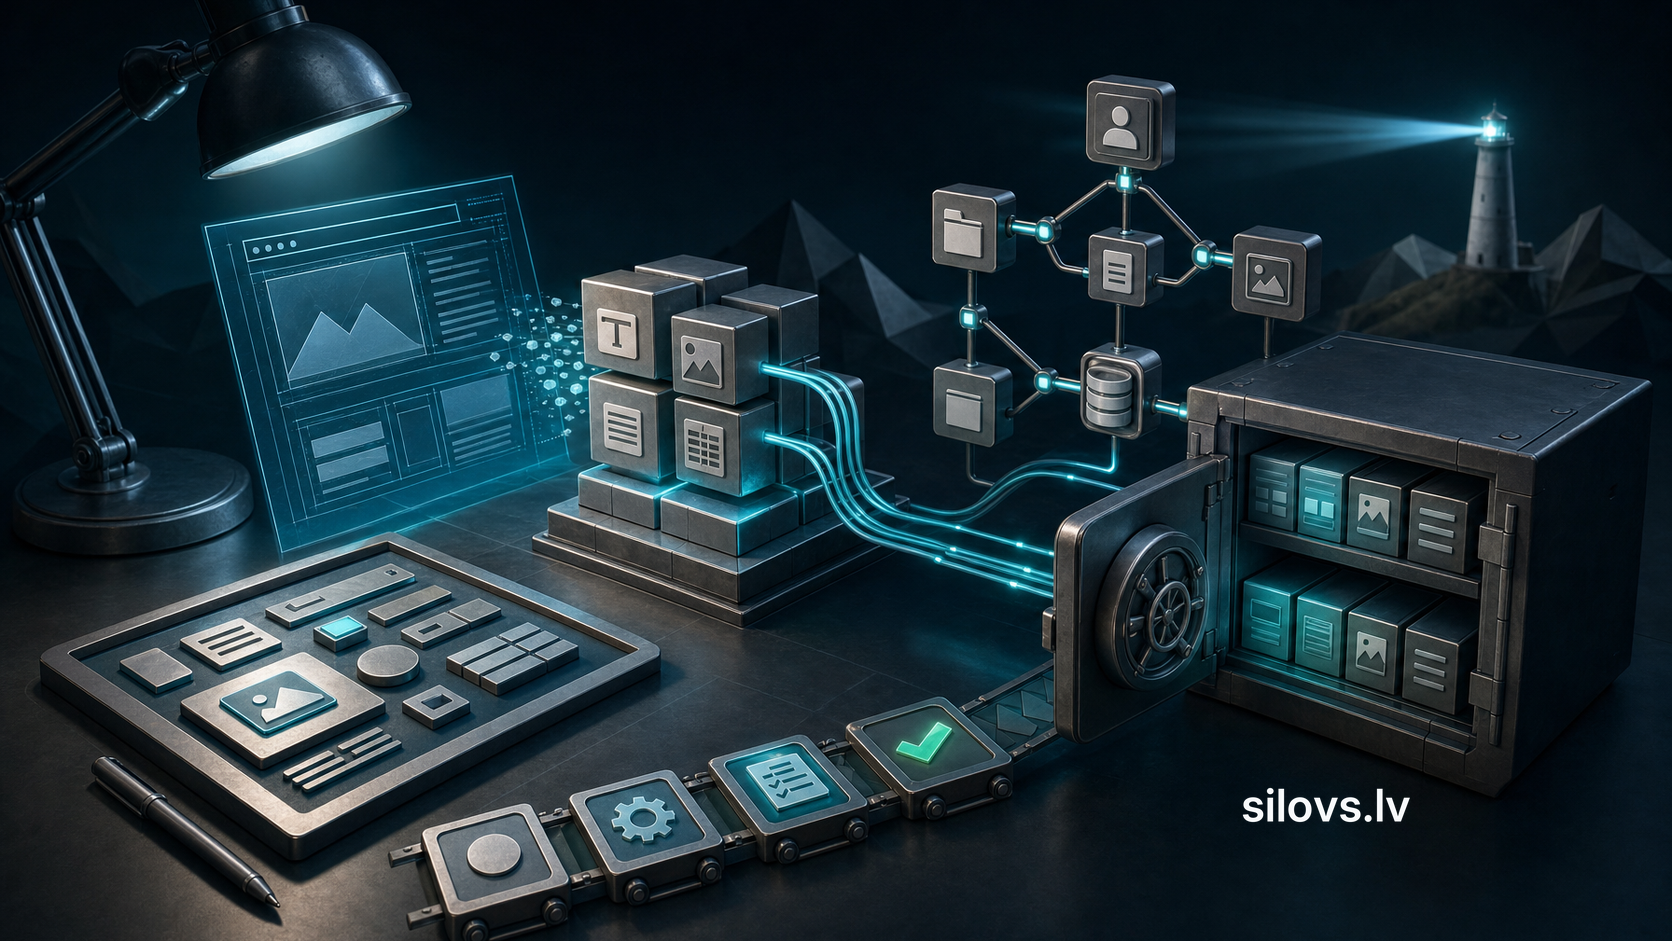
Creating a manageable CMS content model starts with a clear agreement on content objects, their meaning, lifecycle and relationships. Every field needs one understandable purpose, every status needs permitted transitions, and every relationship needs rules for cardinality, ownership and deletion. Before development begins, create a model catalogue, test it with real content examples and define a process for schema changes. This approach does not make the model immutable; it allows controlled changes without losing the meaning of the data or breaking integrations.
What is a CMS content model?
A CMS content model is a formal description of the content objects stored by a system, the data that describes each object, how the object changes state and how it relates to other objects. The “Article” content type appears to an editor as a form, but within the system it is a set of rules used by the administration interface, public website, search, API, imports and other integrations.
At least four elements should be distinguished in the model:
- entity — a standalone object with its own identity, such as an article, author or service;
- field — a property of an object, such as a title, publication date or price;
- status — the object’s position within a defined workflow or publication process;
- relationship — a structured link between objects, such as an article having an author.
A model ages poorly when these concepts are mixed. Copying an author’s name into a text field may initially seem simple, but it later makes updating the author’s profile more difficult. Conversely, turning every minor choice into a separate entity creates unnecessary administration. The aim is not to create the most complex possible schema, but a structure precise enough for its anticipated uses.
Start with decisions, not the administration form
Before listing fields, determine which decisions and actions will depend on the data. A practical starting sequence is:
- Compile the main content use cases: website publication, filtering, search, reuse, export and transfer to other systems.
- Identify standalone business objects rather than existing page templates.
- Assign each object a stable identifier and a clearly responsible role.
- Describe fields, statuses and relationships independently of any particular CMS screen.
- Test the model using typical, incomplete and edge-case records.
A content type should not be created merely because two pages look different. One structured service object can have several presentations. Conversely, one visually similar template can display different entities with different lifecycles. Design determines presentation; the model determines the meaning of the data.
A useful initial catalogue might look like this:
|
Entity |
Standalone identity |
Responsible role |
Main relationships |
|
Article |
Yes |
Content editor |
Author, categories, related articles |
|
Author |
Yes |
Content manager |
Articles, profile image |
|
Category |
Yes |
Content manager |
Articles, parent category |
|
Media file |
Yes |
Editor or administrator |
Places of use, copyright data |
The table is not yet a database schema. It helps stakeholders agree on the objects before technical implementation.
How to design fields with unambiguous meaning
Document the name, semantics and usage rules of every field. A minimum field description includes:
- an immutable technical name;
- a label and explanation that editors can understand;
- the data type and, where necessary, format;
- permitted values and validation limits;
- whether it is required at a particular lifecycle stage;
- a default value, if there is a business justification for one;
- whether one or multiple values are allowed;
- language and localisation rules;
- conditions governing access, sensitivity and data provenance.
A technical name such as publication_date should preferably be treated as a stable part of the contract. The visible label may change, but changing the technical name can affect API integrations, templates, exports and analytics. Vague names such as extra_text or field_2 pass today’s haste on to future maintainers.
Choose the narrowest data type that matches the meaning. Use a date or date-and-time field for a date value; free text is unsuitable. A fixed business choice should be stored in a controlled set of values because consistent spelling cannot be assumed. A monetary amount also needs a currency; an image may need alternative text, usage-rights information and a focal point.
“Required” does not mean that a field must be completed as soon as an empty draft is created. Some rules can apply during a status transition: an incomplete draft may be saved, but it may only be published after the required data has been checked. This preserves flexibility during the work without lowering the quality requirements for published content.
Structures, types and validation conditions can be described in a machine-readable schema. The JSON Schema specification provides a common foundation for describing the structure and constraints of JSON documents, but the schema itself does not replace agreement on the business meaning of fields.
Statuses should describe the workflow
A status is meaningful only when it is clear what may enter that state, what may leave it and which checks take place during the transition. A simple editorial workflow may contain the following states:
|
Status |
Meaning |
Permitted next action |
|
Draft |
Content is being created |
Submit for review |
|
In review |
Content is awaiting review |
Return or approve |
|
Approved |
Content is ready for publication |
Publish or schedule |
|
Published |
A version is available in a defined channel |
Edit in a new version or archive |
|
Archived |
Content is no longer active |
Restore only through a defined procedure |
For every transition, specify the permitted role, required fields, automated actions and information to retain in the audit trail. For example, when content moves to “Published”, the system can check the title, URL identifier and publication channel, as well as record who performed the action and when.
In a more complex environment, editorial status should be separated from publication state. Content may be approved but not yet published, or published in one channel and scheduled in another. Combining approval, time and channel in one field causes the number of statuses to grow rapidly and makes their meaning unclear. A combined workflow may be sufficient for a small, single-channel website if its limitations are documented.
Data relationships need rules on both sides
Use a relationship when the related object has its own identity, lifecycle or repeated use. An article’s author is normally a separate entity because one author is used by several articles and their profile must be editable in one place. A one-off introductory text, by contrast, is usually a field of the article.
Every relationship should answer five questions:
- What is the cardinality: one-to-one, one-to-many or many-to-many?
- Which side owns the relationship, and where is it edited?
- Does the order matter?
- What happens if the related object is archived or deleted?
- Does the link refer to the current object or to a specific version of it?
Deletion behaviour must not be left to chance. Possible policies include preventing deletion while references exist, leaving an empty link, archiving the object or deleting dependent records in a controlled way. Automatic cascading deletion is appropriate only when the dependent record has no independent meaning without its parent object. Referential integrity can be enforced at database level with foreign keys; the PostgreSQL documentation on constraints describes primary and foreign keys, as well as unique and check constraints.
Not every choice needs a relationship. If a set of values is small, stable and has no additional attributes, a controlled choice field may be sufficient. If a value will later need a translation, description, hierarchy, responsible person or its own archiving process, a separate entity will be more flexible. The decision should be based on anticipated management needs. Ease of implementation alone is not sufficient justification.
Model changes before the first migration
A manageable model is not one that never changes. It is one with a defined change procedure. Before introducing a new field, status or relationship, determine:
- which business scenario requires the change;
- which existing records and integrations will be affected;
- how historical data will be populated;
- whether the old and new structures will temporarily coexist;
- how the migration will be tested and what will happen if it fails;
- when the old field may be declared deprecated and later removed.
Safe field replacement usually happens gradually: create the new field, define the transformation rule, migrate the data, verify the result, switch readers and writers, and remove the old field only after checking its dependencies. An immediate rename in the administration interface may be merely a visual change, or it may be a schema change with wide-ranging consequences—it depends on the CMS implementation.
A content version should be distinguished from a model version. A content version answers what changed in a particular article, while a model version indicates how the data structure itself changed. It is useful for a migration log to retain the schema version, execution time, number of affected records, errors and the transformation rule used. This does not eliminate risk, but it makes the change verifiable.
Practical example: a service content type
Suppose a CMS needs to store a company’s services. A minimum model might include a stable ID, internal name, public title, short summary, structured content blocks, responsible contact person, categories, primary image, SEO fields and publication settings.
Three shortcuts should be avoided here. If the contact person already has a standalone profile, their details should not be copied into several text fields. Entering categories as comma-separated text is unsuitable if they will be used for filtering. Storing the entire page in one unrestricted HTML field is also unsuitable if individual parts will be used in listings, search, structured data or another channel.
At the same time, there is no need to split every sentence into a separate field. Structured content blocks are a reasonable compromise when editors need compositional freedom while the system needs known block types and attributes that can be validated. The model’s level of detail should reflect what the system will actually filter, reuse or pass on.
Before implementation, complete at least several distinct examples: a typical service, a service without a price, a time-limited offer, a service in multiple categories and a record that can be archived. This is not statistical evidence of quality, but a practical way to uncover unanswered questions about the model.
Content model review checklist
Before approving the content model, check:
- whether every entity has a clear identity and owner;
- whether every field has one defined meaning;
- whether technical names are independent of temporary design choices;
- whether required fields are checked at the correct workflow stage;
- whether status transitions, roles and rejection paths are documented;
- whether relationships have cardinality and deletion rules;
- whether localisable and shared data are separated;
- whether API consumers are aware of possible schema changes;
- whether historical data migration has testing and rollback plans;
- whether an editor can understand the form without a verbal explanation from a developer.
After implementation, the health of the model can be assessed through practical signals: types of validation error, unused fields, orphaned links, records stuck in statuses, frequent manual corrections and integration errors following schema changes. These indicators must be interpreted in context. For example, a large number of errors may indicate poor-quality data, an unclear form or an excessively strict rule.
Limitations and risks
A detailed content model is not an end in itself. A simpler structure may be sufficient for a small website with a few pages that rarely change. Premature abstraction creates numerous entities, relationships and editorial tasks with no practical use. Multi-channel publishing, large catalogues and multiple integrations, by contrast, generally require stricter rules and more stable technical identifiers.
A data model alone is not enough for security and governance. Access rights, activity logs, backups, restoration, personal data processing and integration error handling must be designed separately. A database constraint also cannot verify every aspect of business meaning; some rules must be implemented in the application and workflow.
For legal, financial or otherwise regulated data, retention periods, access and deletion cannot be determined solely by the technical team. In such cases, the model must be agreed with those responsible for the relevant domain. If the requirements are not yet known, it is better to document the assumptions and schedule a review point than to present a temporary choice as an immutable truth.
Conclusion
A good CMS content model is an agreement about the meaning of data and the process for change. The number of fields alone does not determine its quality. What matters is the ability to explain clearly what each field means, who may change a status, how objects are related and what will happen during the next schema change. When these answers are documented and tested against real scenarios, the CMS is much easier to maintain even as the team, design or integrations change.